Tensorium
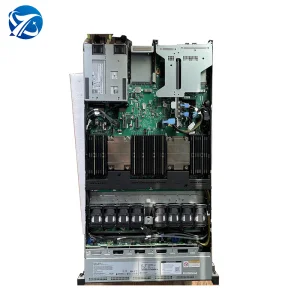
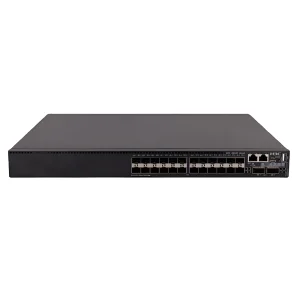
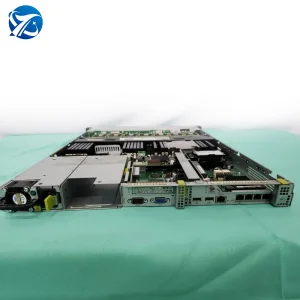
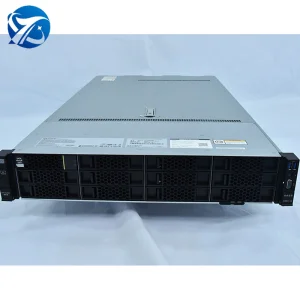
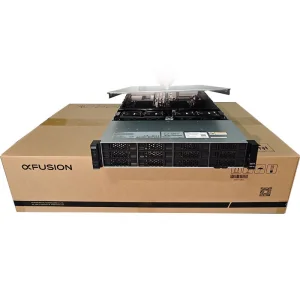
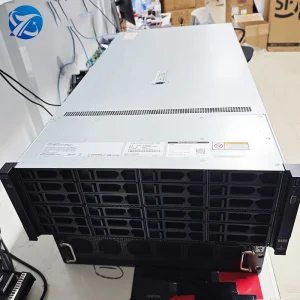
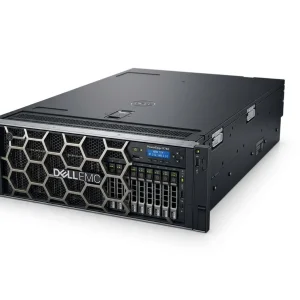
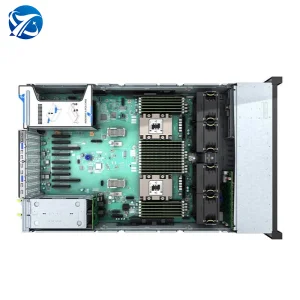
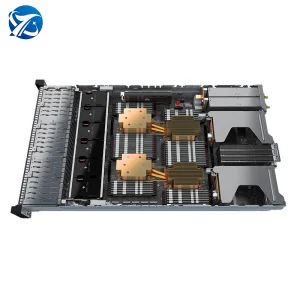
In the rapidly evolving landscape of enterprise computing and Artificial Intelligence, ensuring system resilience under extreme transaction volumes requires a synergy between advanced Server Load Testing Tools and robust hardware infrastructure. As organizations scale out their cloud environments, deep learning model inference clusters, and high-frequency data pipelines, evaluating software performance through tools like Apache JMeter, Gatling, Locust, and K6 is only half the battle. The underlying hardware—ranging from multi-socket rack servers to enterprise-grade NVMe storage and high-throughput optical switches—must be meticulously provisioned to withstand simulated peak loads without latency degradation.
Aligning with Google's Search Quality Rater Guidelines and E-E-A-T (Experience, Expertise, Authoritativeness, and Trustworthiness) standards, this whitepaper examines the top global suppliers, technical roadmaps, localization challenges, and supply chain efficiencies that empower modern data centers. By integrating comprehensive hardware stress testing with advanced software profiling, enterprises can achieve fault-tolerant deployment architectures capable of supporting next-generation AI workloads like DeepSeek and large language model training frameworks.
The convergence of AI inference and cloud-native architecture demands server load testing tools that simulate millions of concurrent asynchronous requests. Future roadmaps focus on AI-driven synthetic load generation, edge-computing performance simulation, and real-time hardware telemetry feedback loops embedded directly into CI/CD pipelines.
Across North America, Europe, and Southeast Asia, digital transformation initiatives require mission-critical systems to maintain 99.999% uptime. Enterprises are heavily investing in robust server infrastructure and rigorous benchmarking tools to eliminate single points of failure, mitigate DDoS vulnerabilities, and optimize cloud expenditure.
Localized server deployments in regional data centers require bespoke load testing strategies that account for regional latency profiles, localized regulatory compliance frameworks, and disparate network bandwidth constraints, ensuring seamless multi-region user experiences.
China's manufacturing ecosystem in Guangdong offers unmatched supply chain agility, rapid prototyping, and vertical integration for high-performance server hardware. With over 1,200 vetted supply chain partners, manufacturers ensure streamlined component sourcing, strict cost optimization, and accelerated delivery schedules for global enterprises seeking scalable AI server clusters.
Global deployment requires adherence to international safety and electromagnetic compatibility standards (CE, FCC, ISO9001). Rigorous burn-in testing, thermal profiling, and comprehensive quality assurance protocols guarantee that every server rack delivered meets enterprise-grade reliability and legal compliance across diverse international jurisdictions.
Founded in 2016, Tensorium Intelligent Technology Co., Ltd. is a professional manufacturer and global supplier of high-performance AI GPU servers, GPU clusters, and intelligent computing infrastructure solutions. We specialize in delivering reliable, scalable, and customized computing platforms for artificial intelligence training, inference, deep learning, HPC, and enterprise data center applications.
Located in Guangdong, China, Tensorium operates a modern manufacturing facility covering over 380㎡ and serves customers across North America, Europe, the Middle East, Southeast Asia, and other global markets. With years of experience in the AI computing industry, we have established a strong reputation for product quality, engineering expertise, and responsive customer service.
Our annual export revenue exceeds USD 18 million, supported by an extensive supply chain network of more than 1,200 trusted partners worldwide. We work closely with AI startups, cloud service providers, system integrators, research institutions, enterprise customers, and data center operators seeking high-performance computing solutions.
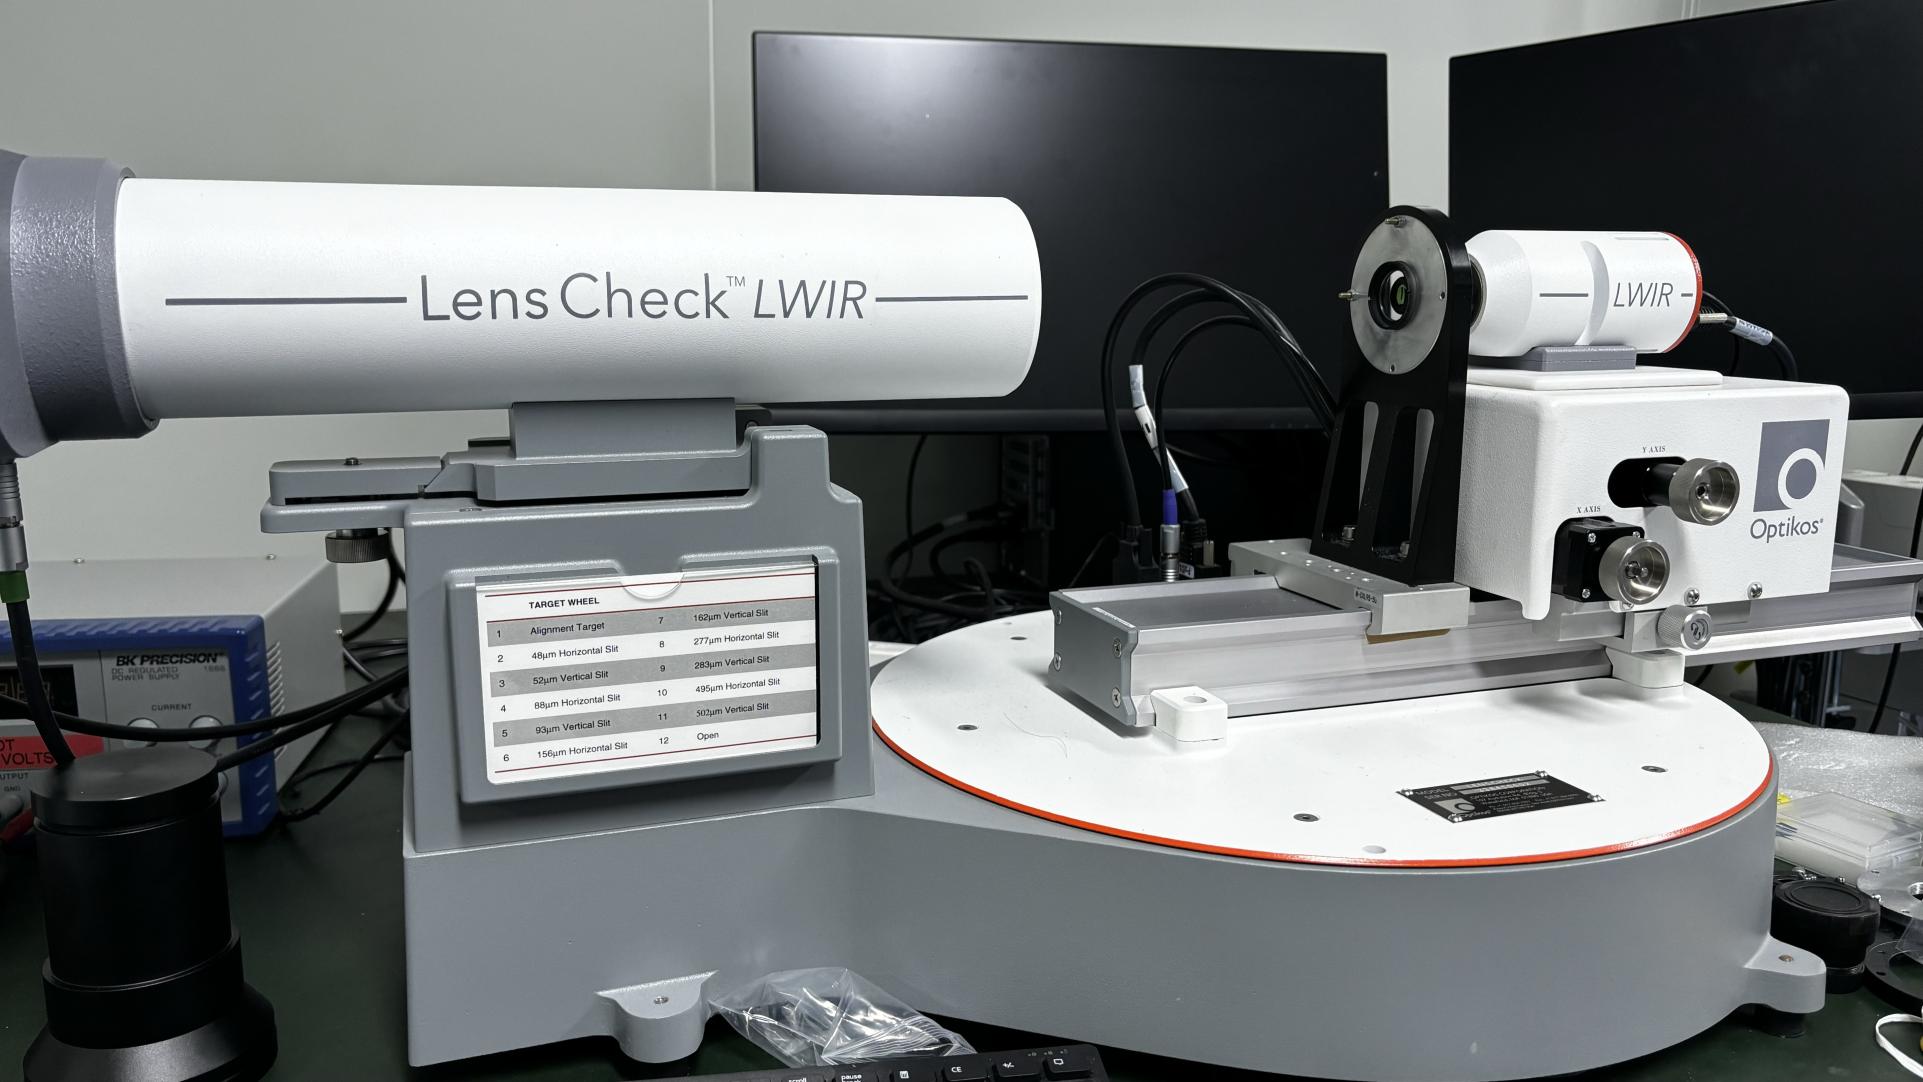
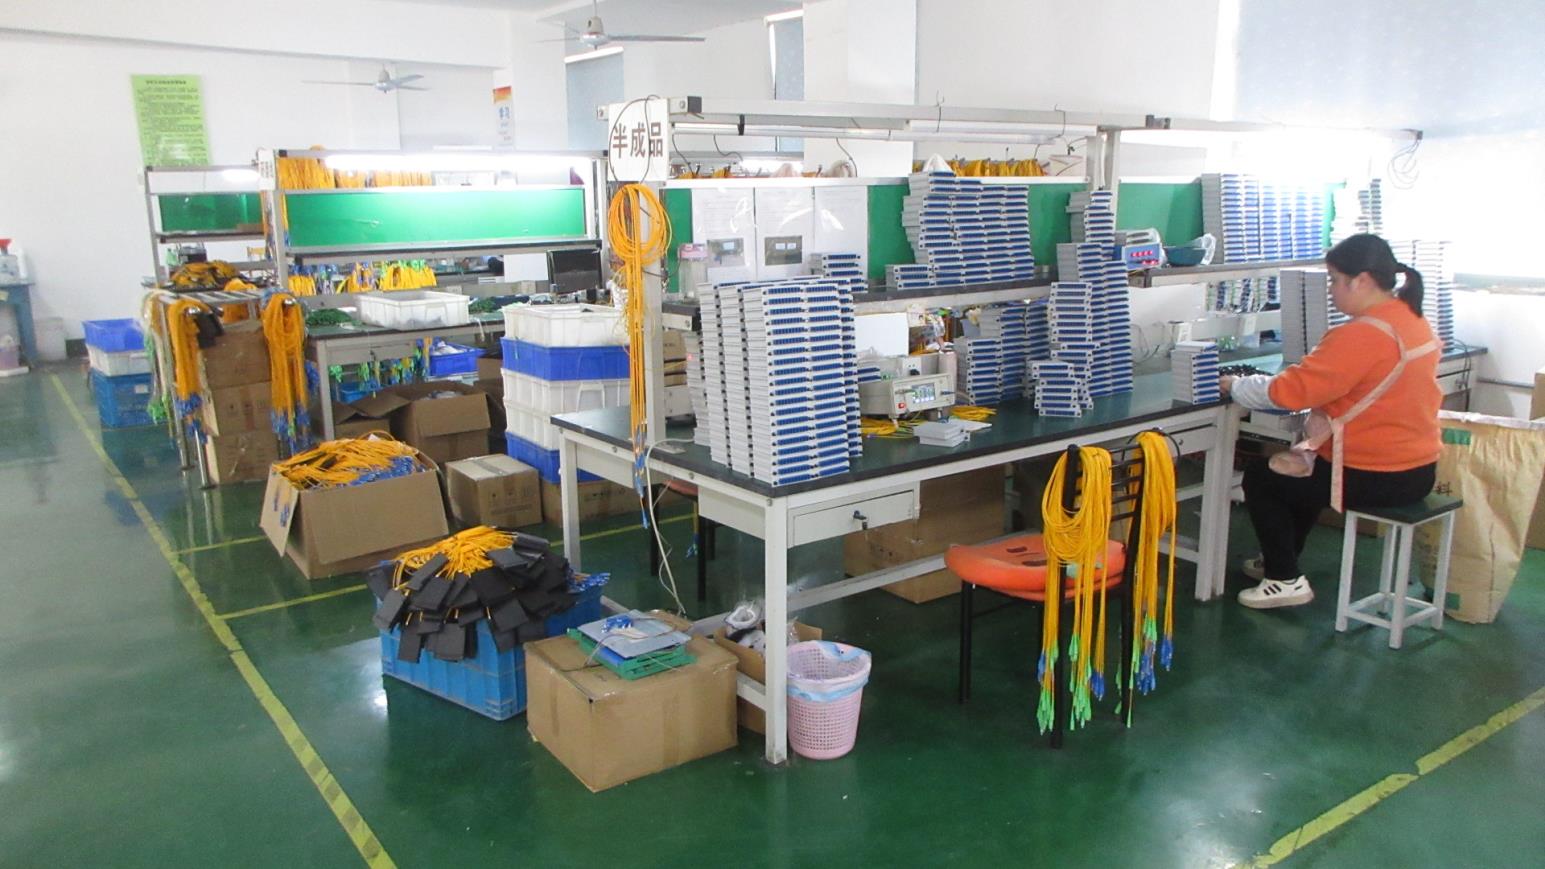
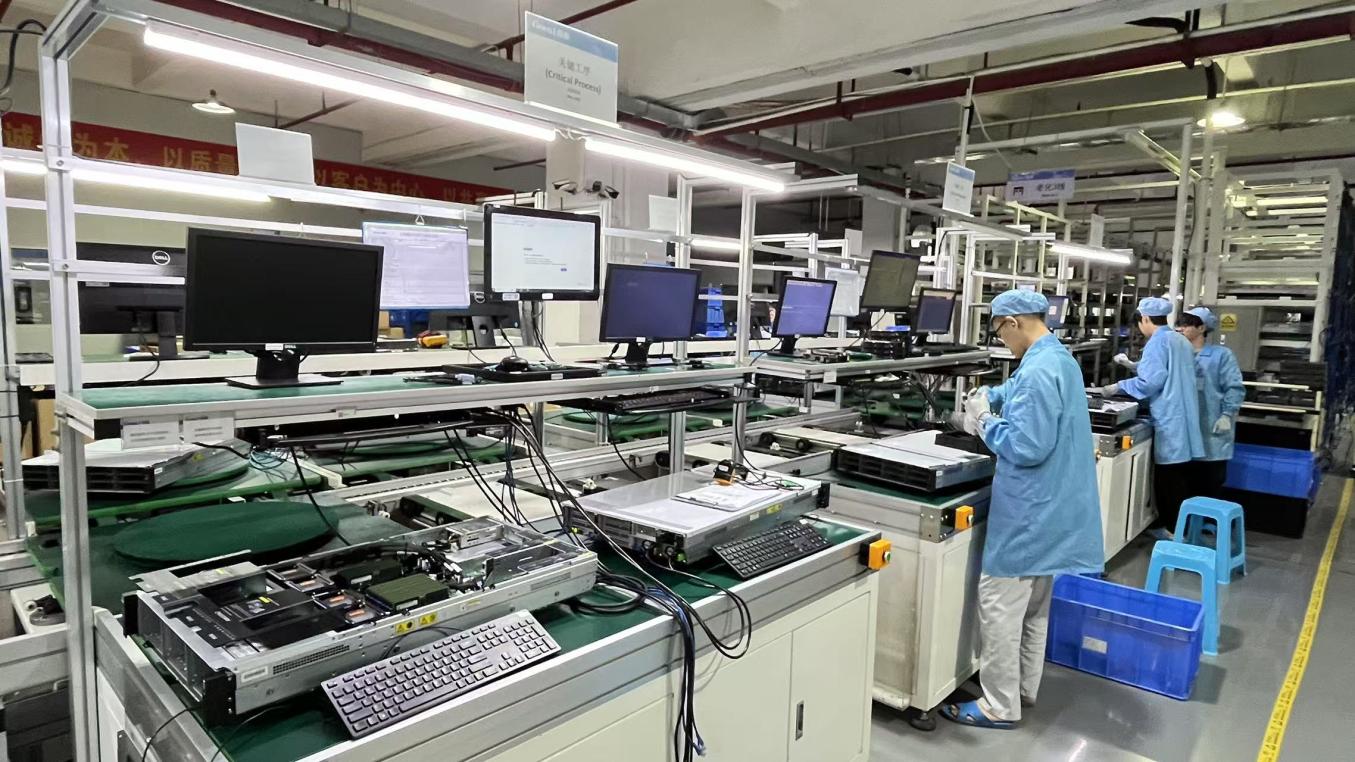
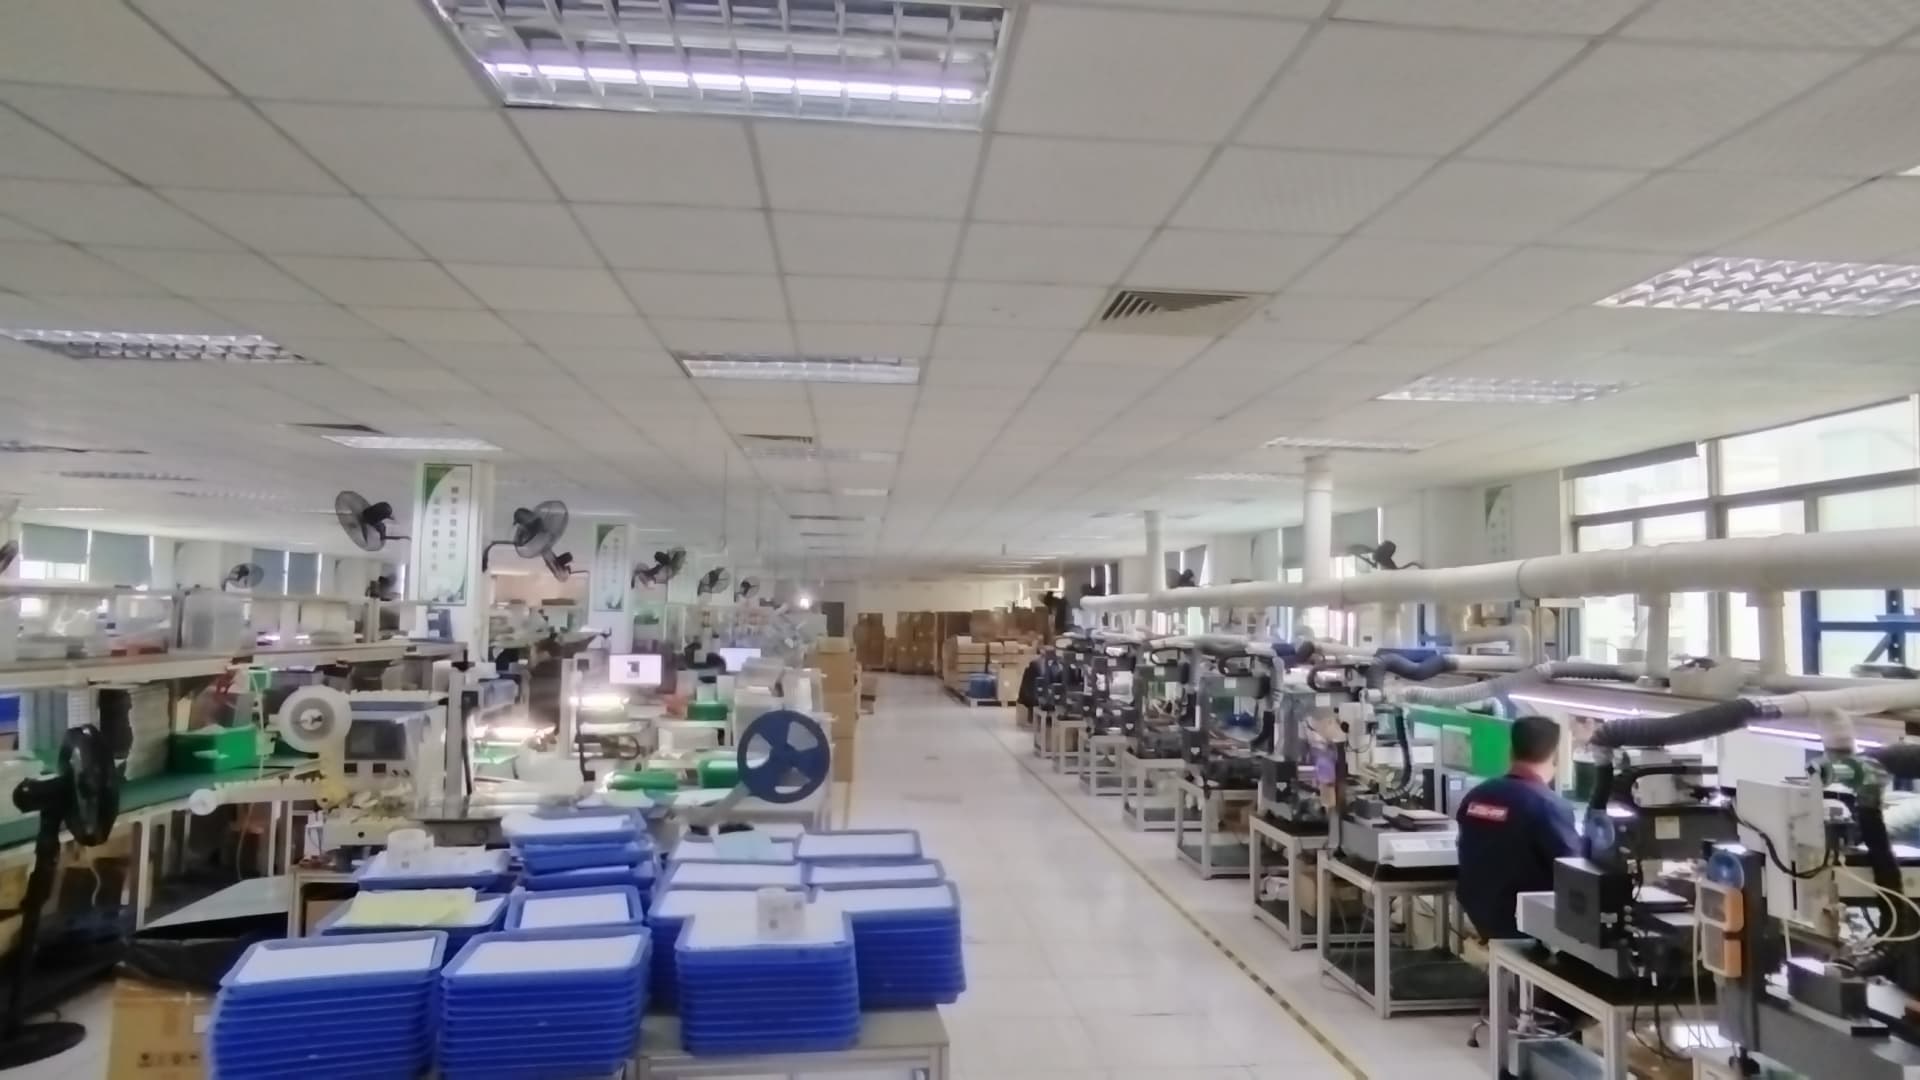
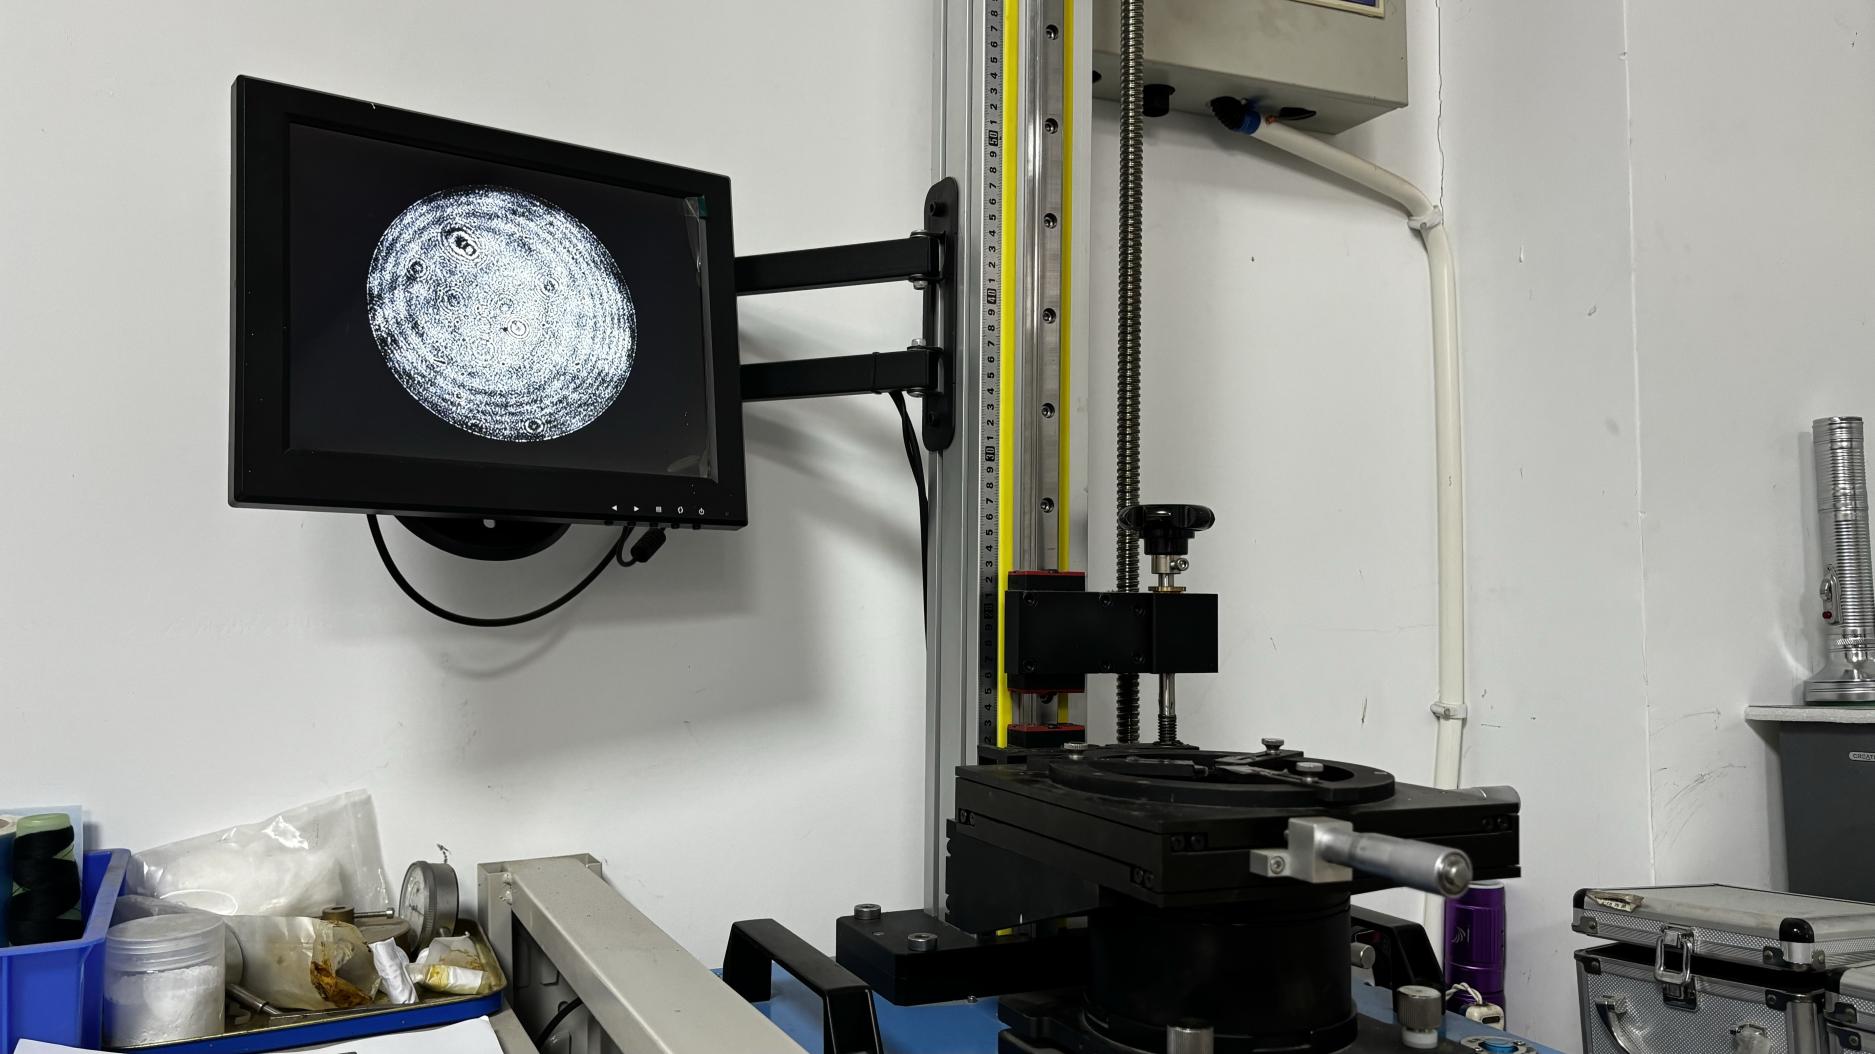
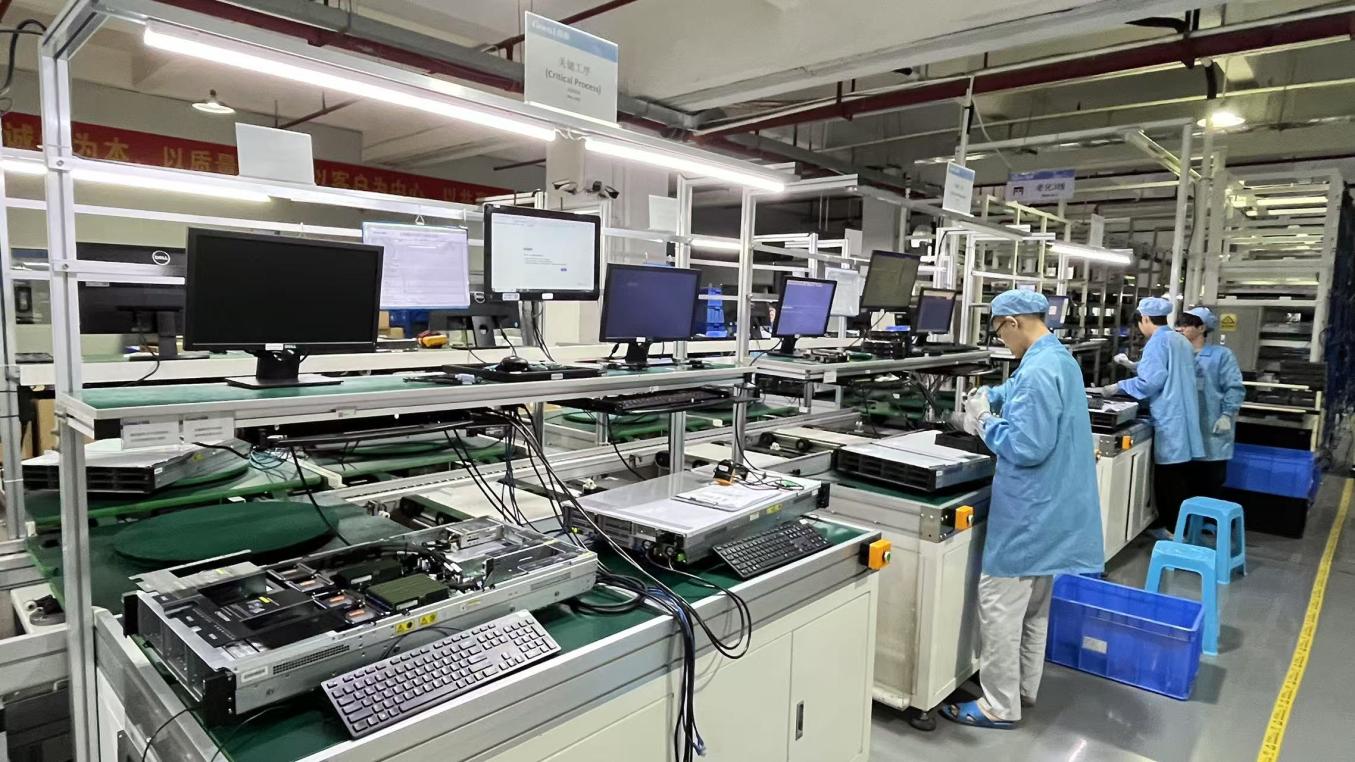
Load testing tools identify performance bottlenecks under simulated peak traffic. Understanding whether a bottleneck stems from CPU throttling, memory latency, or network switch saturation ensures that enterprise buyers invest in the correct server specifications, such as high-core-count Xeon processors, high-speed NVMe SSDs, and optical network switches.
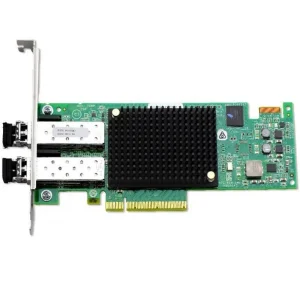
We provide comprehensive hardware customization including GPU configuration (NVIDIA enterprise accelerators), CPU platform selection, custom storage architectures (NVMe/SATA RAID arrays), high-speed networking HBA cards, rack integration, and custom BIOS/firmware branding services.
Every server undergoes a stringent multi-step QA process including component verification, assembly inspection, system integration benchmarking, 24-48 hour burn-in testing, thermal performance validation under full load, and final regulatory compliance checks.
Backed by over 8 years of export experience and 1,200+ supply chain partners, we offer reliable global shipping, localized technical support, standard warranty coverage, and dedicated engineering consultation for seamless enterprise deployment worldwide.